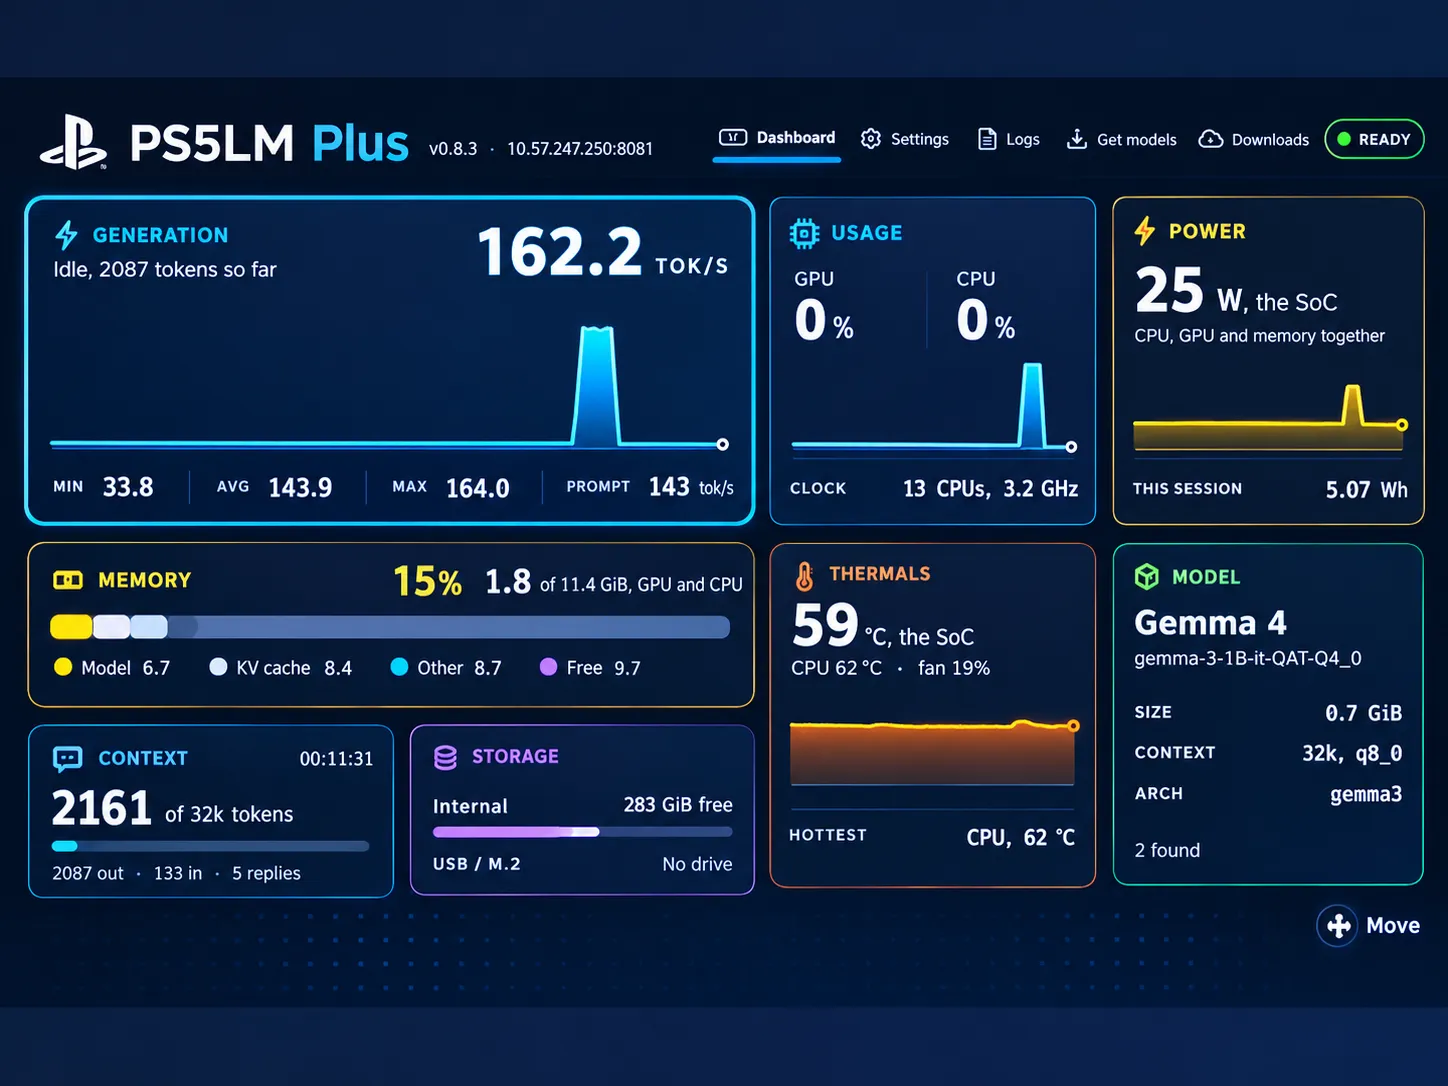
I used PS5LM Plus to try local language models on my jailbroken PlayStation 5. In one recorded Gemma 4 run, I measured approximately 61.1 tokens per second.
The useful question is whether I can reproduce it under documented settings, then compare the models fairly. This notebook does not yet provide that comparison.
What I recorded
I tried Gemma 4 E4B IT in a Q4KM community variant labelled Uncensored HauhauCS Aggressive, Gemma 3 1B in Q4, and Llama 3.2 1B. The 61.1 tok/s observation belongs to the Gemma 4 variant. I have not published comparable timings for the other two.
My informal notes also record 9/10 on a 12-coin puzzle and 8/10 on a model-identity exercise. These were my own checks, not standard benchmarks. Without the prompts and scoring rules, they cannot support a ranking against other models.
What I need to record next
The published record does not yet specify my exact firmware, PS5LM Plus build, model hashes, context size, sampling settings, prompt text, output length or repeated-run statistics. It also does not establish time to first token, sustained speed, memory use or power consumption.
A reproducible follow-up needs those details, identical prompts for each model, saved output, logs or screenshots, timings and failures.
The PS5LM Plus project is the primary source for the software's design. Its results are separate from mine and do not verify my measurements.
For now, the useful result is a working local chat session and one speed observation to investigate further. A matched comparison needs the same prompts, recorded settings and repeated runs.